AI developer tools · What shipped
For a senior engineer who already reads HN. Real changes in AI developer tools today: releases with version numbers, papers with benchmarks, repos that crossed a threshold worth knowing. Skip hype threads, pre-announcement leaks, and recycled summaries. Always link primary sources.
← Zur aktuellen AusgabeKimi K3.1 Pro launches 4th, Haiku 5.5 variants ship
Kimi K3.1 Pro: 4th on index
Moonshot's new model closes the gap on frontier labs.
Kimi K3.1 Pro scored 55 on the Artificial Analysis Intelligence Index, landing 4th overall with gains across agentic benchmarks: 67% on Terminal-Bench 4.0 and 73% on AutomationBench-AA [Quelle: Artificial Analysis]. It ships 1M token context, 104B active parameters, multimodal input, and 33% lower pricing than K3 at $2/$10/$0.20 per million input/output/cache tokens. Open-weights release is imminent, which would make it the highest-scoring public model and shrink the proprietary-to-open gap from 12 to 3 points on the index.
The open-source ceiling just rose.
Haiku 5.5: Five tiers, one tradeoff space
Anthropic's stratification strategy deepens following previous issue.
Five Haiku 5.5 models now tile the cost-versus-capability plane: Max reaches 43 on the Intelligence Index with 235 tokens/sec and $0.12/input pricing; Low hits 6.68s time-to-first-token at $0.02 per task [Quelle: Artificial Analysis]. Pricing spreads 8.7x across variants, letting teams dial per-workload instead of forcing one tier across all inference. The Intelligence Index v4.3.2 now spans 10 benchmarks covering finance, legal, healthcare, engineering, and reasoning domains—finer resolution than prior snapshots.
Commodity AI infrastructure just became workload-specific.
Agentic benchmarks gain teeth
Real-world agent capability now has a scorecard.
The Artificial Analysis evaluation suite now isolates agentic performance through Terminal-Bench 4.0 (command-line reasoning), AutomationBench-AA (task automation), and personality profiling—moving beyond static knowledge tests [Quelle: Artificial Analysis]. Kimi K3.1 Pro's 73% on AutomationBench-AA and strong Terminal-Bench results show how multi-step reasoning now ranks alongside coding and math. The shift from memorization leaderboards to agent-task benchmarks reflects what production teams actually measure.
Benchmark gravity is shifting toward what engineers ship.
 Claude Haiku 5.5: Release Intelligence, Performance & Price6 hours ago ... The Claude Haiku 5.5 release offers 5 models, each with different intelligence, performance ... AI Agents · Evaluations. Products. Optima · MicroEvals · Model ...artificialanalysis.ai
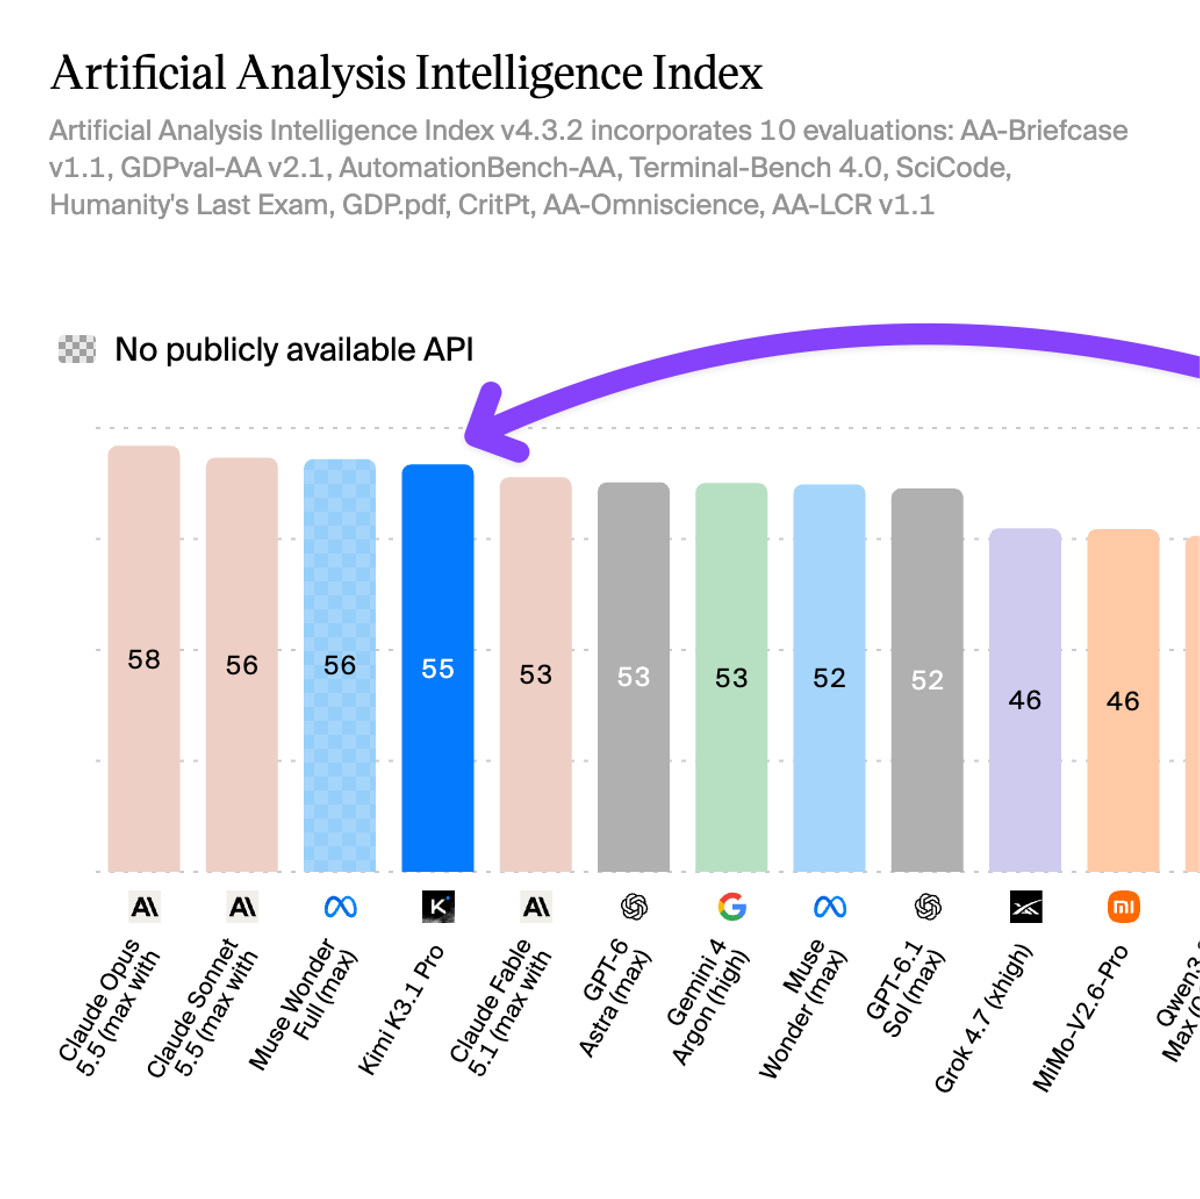 Kimi K3.1 Pro launches at 4th on the Intelligence Index and will lead ...11 hours ago ... 1 Pro are released it will be the highest-scoring open weights model and ... benchmarks evaluating how AI models respond in realistic health conversations.artificialanalysis.ai