Du wirst angemeldet...

Bitte warte, während wir deine Anmeldung überprüfen

Artikel · Samstag, 26. September 2026

AI developer tools · What shipped

For a senior engineer who already reads HN. Real changes in AI developer tools today: releases with version numbers, papers with benchmarks, repos that crossed a threshold worth knowing. Skip hype threads, pre-announcement leaks, and recycled summaries. Always link primary sources.

Von Marius BongartsTech81 Ausgaben
← Zur aktuellen Ausgabe
Ausgaben
12 / 81
Über Nacht von KI aus öffentlichen Quellen erstellt, täglich aktualisiert.
AI developer tools · What shipped
Samstag, 26. September 2026
AI developer tools · What shipped

Fable 5.1 holds lead; smaller models ship; KV cache compression arrives

2 Min. Lesezeit

Fable 5.1 & Mythos 5.1

Agentic coding just stayed cheap and got sharper.

Following previous issue, Fable 5.1 confirms its benchmarks and Mythos 5.1—the permissive-safeguard variant—ships with production-grade biotech capabilities [Source: Anthropic]. Mythos reaches 50% hit rate on protein binder design (versus 10–15% baseline) and delivers GPU kernel speedups up to 2.5× for genomics workloads, plus the model now runs high-resolution elevation mapping tasks that required specialized pipelines before. Both land with Enterprise Frontier Safeguards for zero-data-retention on-prem deployments.

Security and life sciences orgs now have first-class tooling.

Jan-Code-4B

Four billion parameters, local inference, beats bigger models.

Jan released Jan-Code-4B, a lightweight code model fine-tuned for consumer hardware that outperforms Jan's own prior 4B variant and Qwen3-4B-Instruct across three coding benchmarks: Aider (19.0 vs. 18.0), LiveCode Bench v6 (51.0 vs. 45.8), and AIME25 math reasoning (53.0 vs. 47.0) [Source: Jan.ai]. It runs on 8GB minimum RAM with quantized variants, ships OpenAI-compatible API access, and supports code generation, refactoring, debugging, and agentic workflows via vLLM or llama.cpp.

Local-first teams just cut cloud inference costs to zero.

MILO KV cache compression

Many-shot context just got 50% smaller in memory.

MILO, a block-wise low-rank KV cache compression framework published on arXiv, exploits redundancy in key-value caches to achieve up to 50% memory reduction and 1.8× throughput gain on Qwen2.5 models [Source: arXiv]. Dynamic rank allocation uses information entropy; system optimizations include fused Triton kernels and CUDA graphs. Benchmarks show the method outperforms prior baselines like ASVD and Palu by up to 4.5% accuracy on classification and reasoning tasks.

Long-context inference just crossed an efficiency inflection point.

Aikido Altar-1 security model

Pentesting model shrinks 78%, runs on four GPUs, stays sharp.

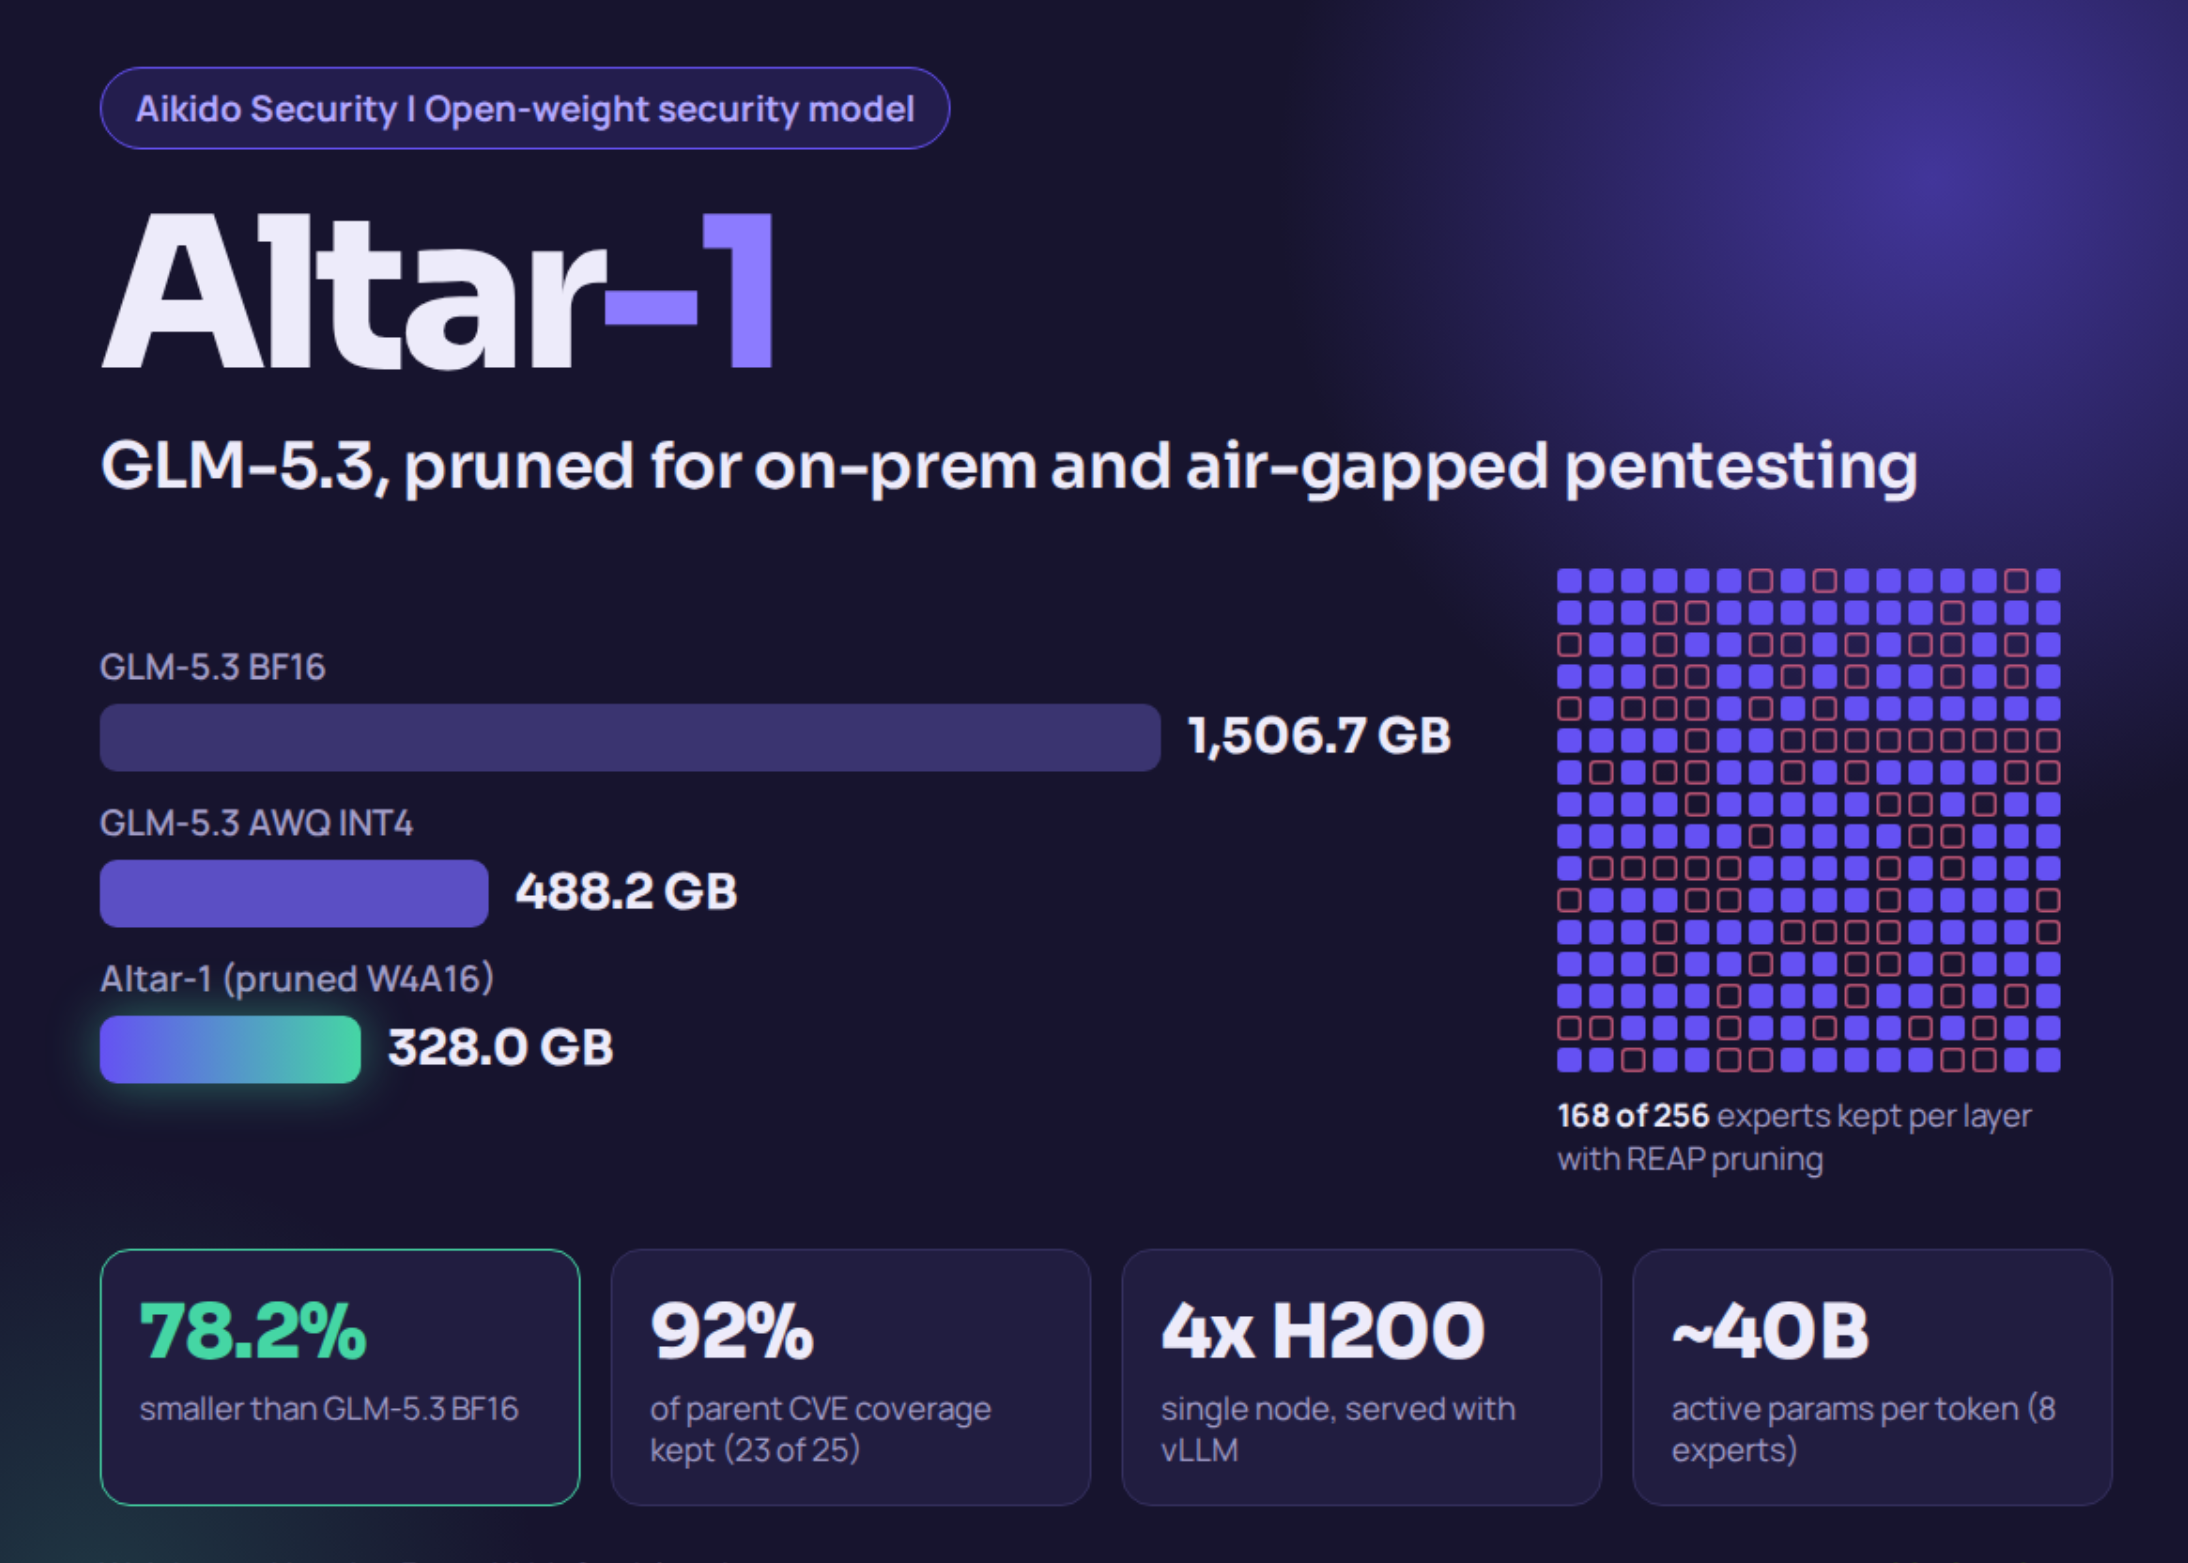
Aikido Security released Altar-1, a quantized and pruned variant of Z.AI's GLM-5.3 (753B) compressed from 1.51 TB to 328 GB while retaining 92% CVE coverage [Source: MarkTechPost]. It runs on a single 4× H200 node with 131k context length; weights are public on Hugging Face under the GLM-5.3 license. Recall on the internal 32-CVE benchmark sits at 60.4%, down negligibly from 65.6% on the full model.

Air-gapped security teams can now host frontier-class vulnerability detection locally.
Quellen
Introducing Claude Fable 5.1 and Claude Mythos 5.1 - Anthropic
2 hours ago ... ... model releases. A small number of customers' custom integrations will then ... AI Act's Code of Practice on Transparency of AI-Generated Content. This ...
anthropic.com
KI-Zusammenfassung

Anthropic released Claude Fable 5.1 and Claude Mythos 5.1, advancing AI code generation and developer tools. Fable 5.1 achieves significantly improved performance on multiple coding benchmarks: 73.4% on CursorBench 3.2.0 (vs 70.5% for Fable 5), 55.8% on Terminal-Bench 4.0 agentic coding, and 60.9% on Humanity's Last Exam with tools. The model demonstrates 25% lower costs for typical workloads and up to 45% savings for agentic work due to 75% reduced cache read pricing ($0.25 per million tokens). Key improvements include enhanced capabilities for long-running problem-solving, better root-cause analysis in debugging, and reduced false positives in safeguards—cybersecurity safeguards now fire 60% fewer times on benign content while supporting vulnerability discovery work. Mythos 5.1 (same underlying model with permissive safeguards) showed exceptional performance on scientific tasks: designing protein binders with hit rates near 50% (vs typical 10-15%), optimizing GPU kernels for genomics models up to 2.5x faster, and creating high-resolution Venus elevation maps. The models are available on all major platforms with API access via claude-fable-5-1, while Mythos 5.1 requires trusted access through cybersecurity and life sciences verification programs.

Quelle öffnen
MILO: Efficient Many-shot In-Context Learning with Block-wise Low ...
20 hours ago ... Inference Optimization for Many-Shot ICL. Despite the promising results of ... Chen ShadowKV: kv cache in shadows for high-throughput long-context llm inference.
arxiv.org
KI-Zusammenfassung

MILO: A block-wise low-rank KV cache compression framework for efficient many-shot in-context learning. The paper addresses the memory bottleneck in many-shot ICL by exploiting low-rank redundancy in key-value caches. MILO achieves up to 50% KV cache memory reduction and 1.8x throughput improvement on Qwen2.5 models through block-wise compression with dynamic rank allocation based on information entropy. Experiments on classification and reasoning benchmarks show the method outperforms prior baselines like ASVD and Palu by up to 4.5% accuracy while maintaining negligible performance degradation. System optimizations include fused Triton kernels, CUDA streams, and CUDA graphs for efficient reconstruction during inference.

Quelle öffnen
Jan-Code-4B - Jan.ai
16 hours ago ... Overview ; Parameters, 4B ; Base Model, Jan-v3-4B-base-instruct (Qwen3-4B-Instruct-2507) ; Fine-tuning focus, Code generation, editing, refactoring, debugging.
jan.ai
KI-Zusammenfassung

Jan released Jan-Code-4B, a lightweight 4B parameter code generation model fine-tuned for fast local inference on consumer hardware. The model outperforms Jan-v3-4B-base-instruct and Qwen3-4B-Instruct across three coding benchmarks: Aider (19.0 vs 18.0), Livecode Bench v6 (51.0 vs 45.8), and AIME25 math reasoning (53.0 vs 47.0). Jan-Code-4B supports code generation, editing, refactoring, debugging, and agentic workflows with OpenAI-compatible API access, running on 8GB minimum RAM with quantized variants and deployment options via vLLM or llama.cpp.

Quelle öffnen
Aikido Security Releases Altar-1: An Open-Weight ... - MarkTechPost
14 hours ago ... ... code --max-model-len 131072. vLLM selects the Marlin MoE kernel ... Altar-1 also powers Aikido Attack, AI Code Analysis, and Deep Review. Next ...
marktechpost.com
KI-Zusammenfassung

Aikido Security released Altar-1, an open-weight security model compressed from Z.AI's GLM-5.3 (753B parameters) to 328 GB through quantization (W4A16) and expert pruning using Cerebras REAP, reducing model size by 78.2% while retaining 92% of CVE coverage. The model runs on a single node of 4x NVIDIA H200 GPUs with vLLM, supports 131k context length, and achieved 60.4% average recall on Aikido's internal 32-CVE benchmark versus 65.6% for the full BF16 parent model, with negligible fidelity divergence (0.506 nats KL divergence). Weights are publicly available on Hugging Face under the GLM-5.3 license, enabling on-premise and air-gapped deployments for organizations with data-residency requirements.

Quelle öffnen
Über Nacht zusammengestellt von MorningMail.aiZugestellt um 05:10