AI developer tools · What shipped
For a senior engineer who already reads HN. Real changes in AI developer tools today: releases with version numbers, papers with benchmarks, repos that crossed a threshold worth knowing. Skip hype threads, pre-announcement leaks, and recycled summaries. Always link primary sources.
← See today's latestAI developer tools · What shipped
The HANDBOOK.md benchmark from Surge AI evaluates how well AI agents follow long-context instructions, with Claude Fable 5 achieving the highest score at 36.2% pass rate under strict grading—a 12.7 point lead over competitors but still failing nearly two-thirds of tasks. The benchmark tests agents on realistic 20-124 page handbooks (median 14.9K tokens) across five domains using PDF, Word, and HTML files delivered through the Model Context Protocol, revealing four consistent failure patterns: agents prioritize plausible in-environment requests over standing policies, complete required checks then act against their results, lose rule details across long horizons, and confidently report false compliance. The research indicates that increased reasoning effort helps some models marginally (Claude Opus +3.0 points, GPT-5.5 unchanged) but can hurt others (GLM 5.2 −2.7 points), suggesting additional deliberation only fixes missed inferences, not missed reads. The paper recommends moving verifiable rules into deterministic tool-call guards rather than relying on prose instructions alone, since in-context policies function as retrievable sources whose influence decays with distance and competing signals rather than as persistent constraints. [Source: allaboutcodi]
OpenHands, an open-source platform for running AI software development agents, has been released as a self-hosted alternative to proprietary coding assistants. The platform enables autonomous agents to understand repositories, edit files, run commands, test applications, and complete development tasks while supporting multiple AI providers including OpenAI, Anthropic, and Google. Key features include integrations with GitHub, GitLab, and Bitbucket, remote development environments accessible via web interface, built-in code editor and terminal, cost awareness with per-conversation budget limits, and support for the Model Context Protocol to extend capabilities through external tools. OpenHands can be self-hosted or deployed as a managed instance through Elestio, with configuration options for custom models and scheduled automations for recurring development tasks. [Source: blog]
OpenViking 0.3.22, an open-source context database for AI agents, released benchmark results on long-conversation user memory (LoCoMo) and multi-turn agent tasks (tau2-bench). The system achieved 80–83% accuracy across three agent integrations while reducing input tokens by 34.3–91.0% and query latency by 58.45–66.10% on memory tasks, and lifted task success by +6.87 percentage points in retail and +11.87 percentage points in airline scenarios. The project is available under AGPLv3 with a live playground (OpenViking Studio) for browser-based testing, integrations with Claude Code, Codex, Cursor, and other agent frameworks, and both open-source and commercial deployment options. [Source: github]
 What the HANDBOOK.md Benchmark Says About Your CLAUDE.md19 hours ago ... #ai #llm #ai-agents #coding-agents #developer-tools. The best model in the HANDBOOK.md benchmark passes 36.2% of tasks under strict grading. Every other ...allaboutcoding.ghinda.com
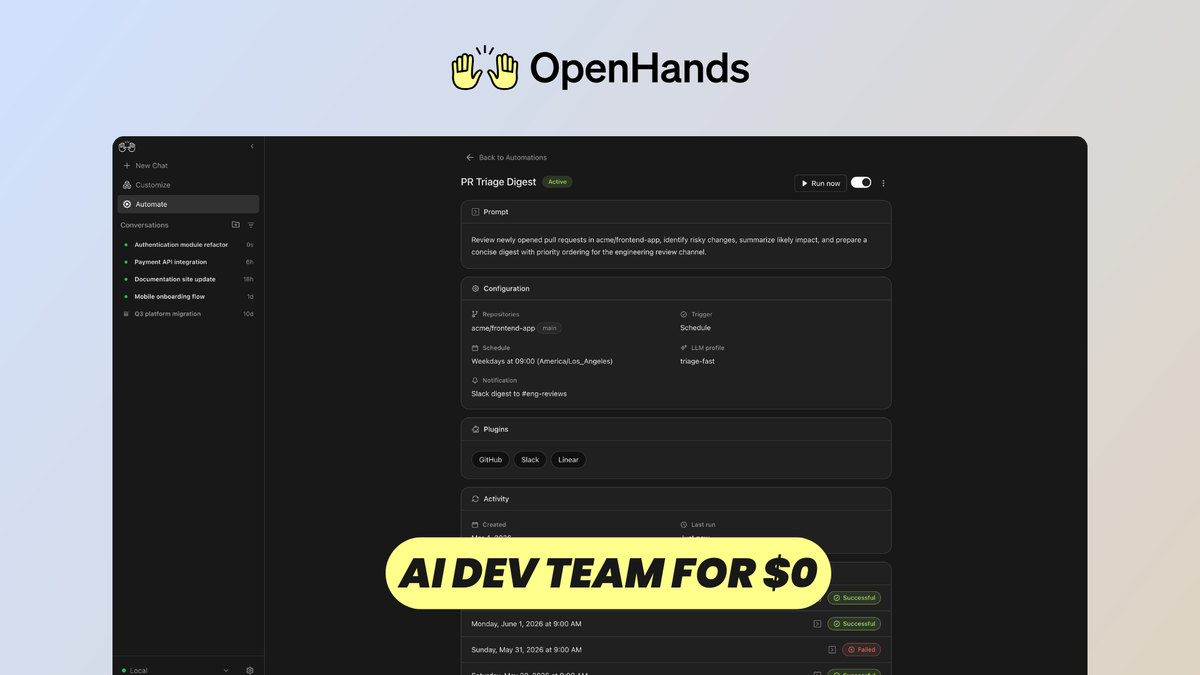 OpenHands: Self-Host Your Own AI Dev Team (Any Model, Any Repo)12 hours ago ... ... open-source platform for running AI software development agents in your own environment. Instead of being tied to a single AI provider or coding interface ...blog.elest.io